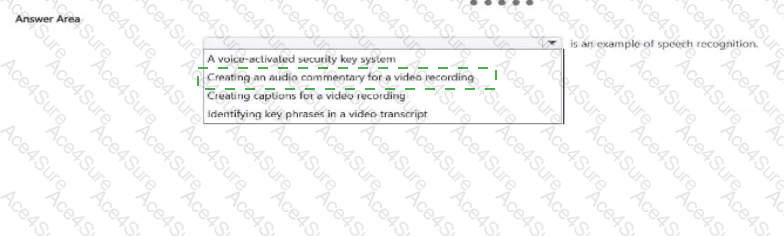
Select the answer that correctly completes the sentence.
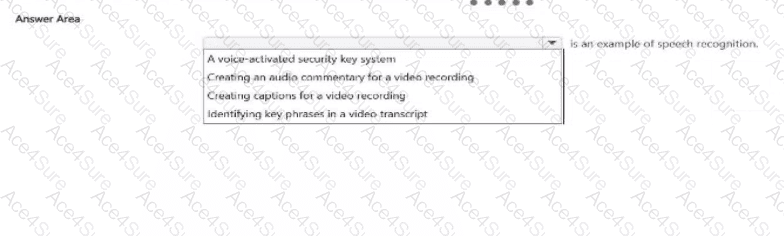
The Answer Is:
Answer:
This question includes an explanation.
Explanation:
The correct answer is Creating captions for a video recording . Speech recognition, also called speech-to-text , converts spoken audio into textual output. Microsoft explicitly defines Azure Speech-to-Text as speech recognition technology that transcribes audio streams or prerecorded audio into text.
Caption generation is a direct application of this capability. Microsoft describes captioning as converting the audio content of a video, film, webcast, or other production into text and displaying that text visually. Therefore, creating captions from the spoken content of a video is a canonical speech-recognition workload.
Creating an audio commentary is instead associated with speech synthesis or text-to-speech because the required output is spoken audio. Identifying key phrases in a video transcript is a text-analysis/NLP task performed after the speech has already been transcribed. A voice-activated security system may involve voice authentication, speaker recognition, or command recognition, but it is not as unambiguously a speech-to-text workload as caption generation.
The AI-901 Study Guide specifically requires candidates to distinguish the features and capabilities of speech recognition and speech synthesis .
AI-901 PDF/Engine
Printable Format
Value of Money
100% Pass Assurance
Verified Answers
Researched by Industry Experts
Based on Real Exams Scenarios
100% Real Questions
Get 65% Discount on All Products,
Use Coupon: "ac4s65"